Infrastructure for synthetic health data
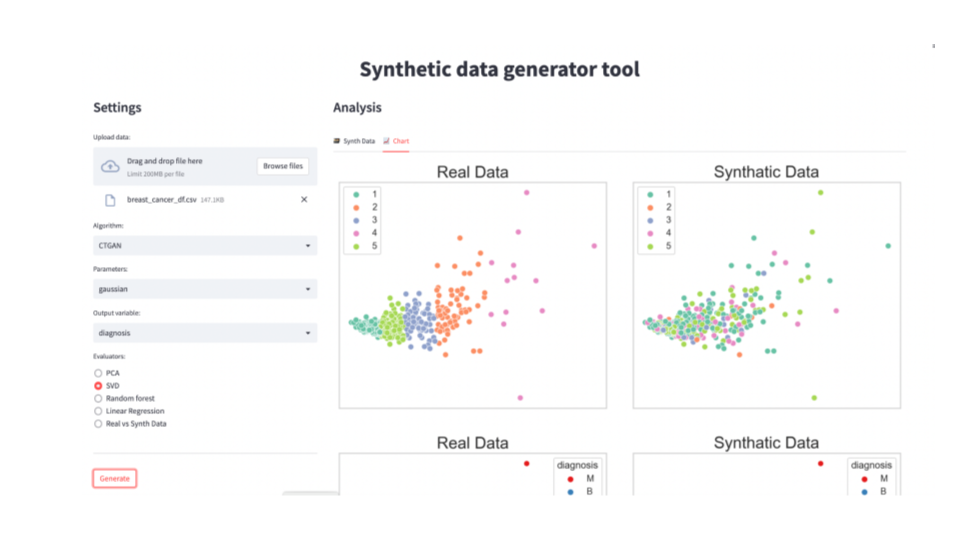
Machine learning (ML) methods are becoming ever more prevalent across all domains of lifesciences. However, a key component of effective ML is the availability of large datasets thatare diverse and representative. In the context of health systems, with significant heterogeneityof clinical phenotypes and diversity of healthcare systems, there exists a necessity to developand refine unbiased and fair ML models. Synthetic data are increasingly being used to protectthe patient’s right to privacy and overcome the paucity of annotated open-access medical data. Here, we present our proof of concept for the generation of synthetic health data and our proposed FAIR implementation of the generated synthetic datasets. The work was developed during and after the one-week-long BioHackathon Europe, by together 20 participants (10 new to the project), from different countries (NL, ES, LU, UK, GR, FL, DE, . . . ).
Figures