SPARQL services for InterMine databases
InterMine is an open source data warehouse system that can be used to create biological databases that can be accessed via web query tools. There are many public InterMine instances that are currently deployed worldwide and they share a core data model pertaining to common biological entities. Besides the core data model, each instance of InterMine typically has an extended data model to cover data specific to that particular deployment. The data is organised according to the graph-based data model but exists in a relational store (Postgres). The goal of this project was to explore the possibility of translating InterMine data from relational form to a graph form using Resource Description Framework (RDF) as the exchange format. This could provide a route to exposing data from InterMine instances as RDF triples and thus making it possible to query the data using the SPARQL Protocol and RDF Querying Language (SPARQL).
Figures
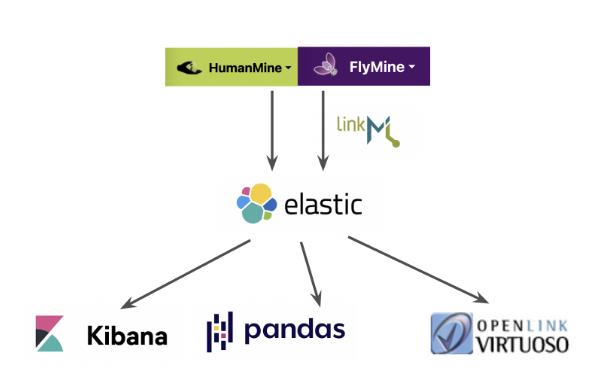
Figure 1: Overview of workflow. The data models from HumanMine and FlyMine were extracted in JSON and converted to Li...
Figure 1: Overview of workflow. The data models from HumanMine and FlyMine were extracted in JSON and converted to LinkML YAML. JSON data for objects from the Gene, Protein and Disease classes were converted to RDF-compliant JSON-LD and loaded into Elasticsearch. This enabled data exploration and analysis using Kibana and Pandas, as well as facilitating conversion to triples that were loaded into Virtuoso.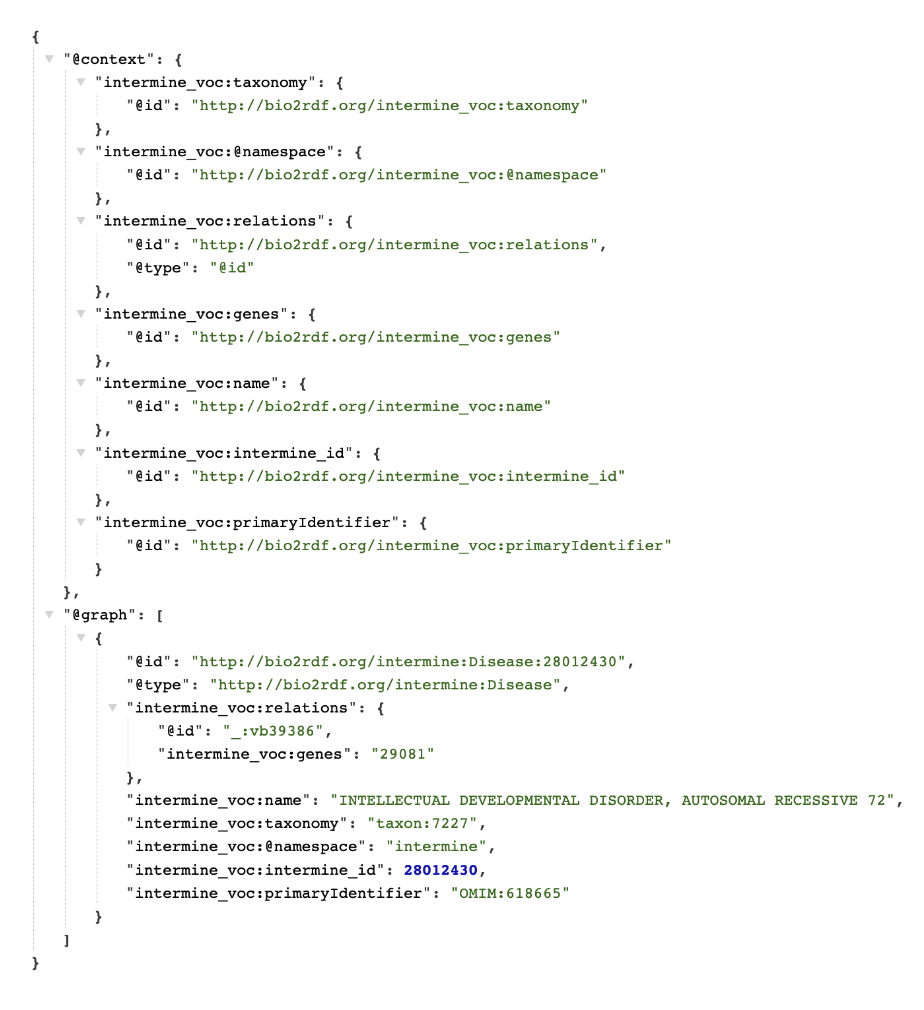
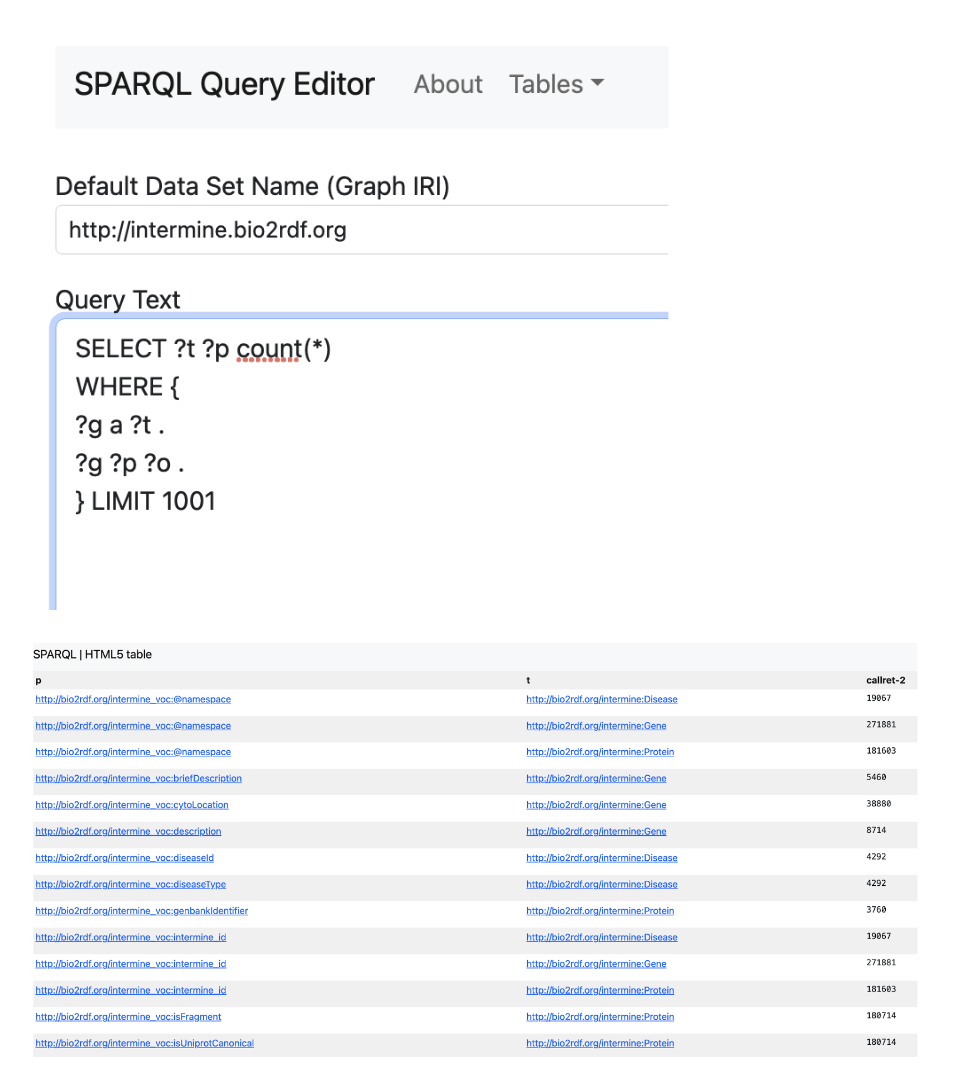
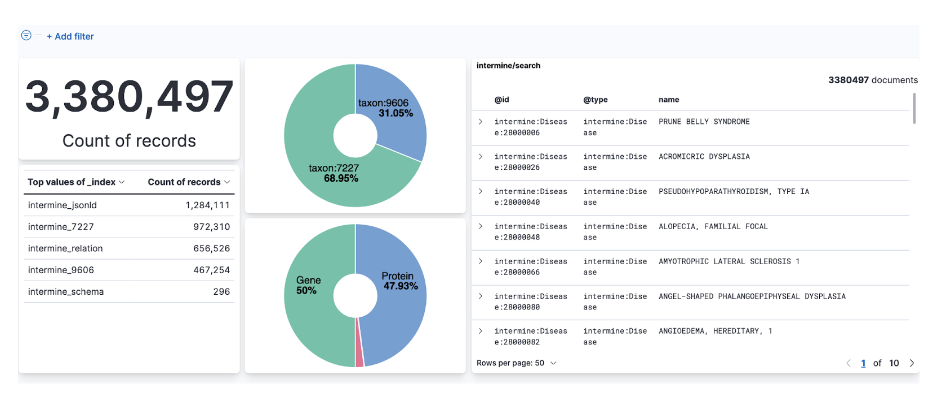
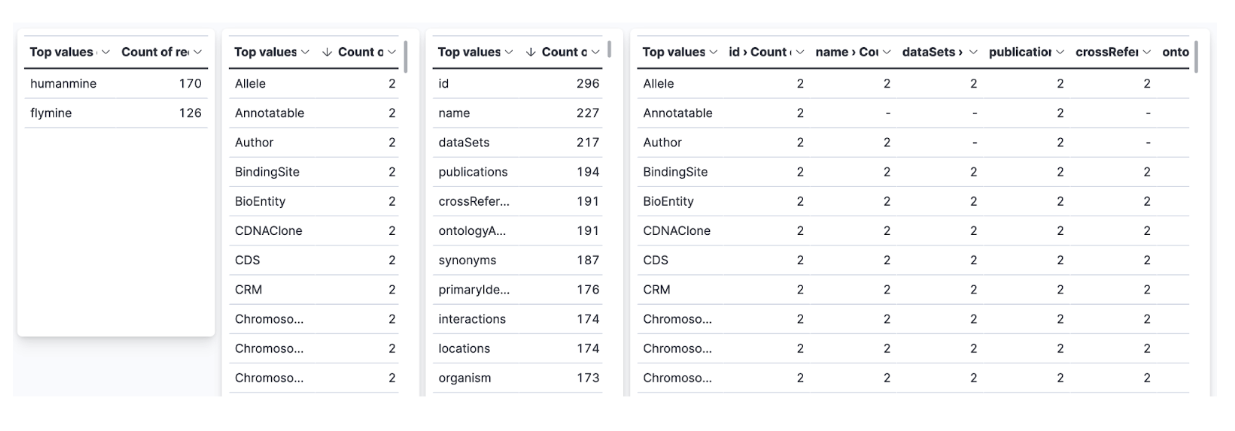
Figure 4: Kibana running over the data in Elasticsearch was used to summarise the number of records from each databas...
Figure 4: Kibana running over the data in Elasticsearch was used to summarise the number of records from each database, including by taxon, and to allow the documents to be browsed.